Last updated:

Model generation
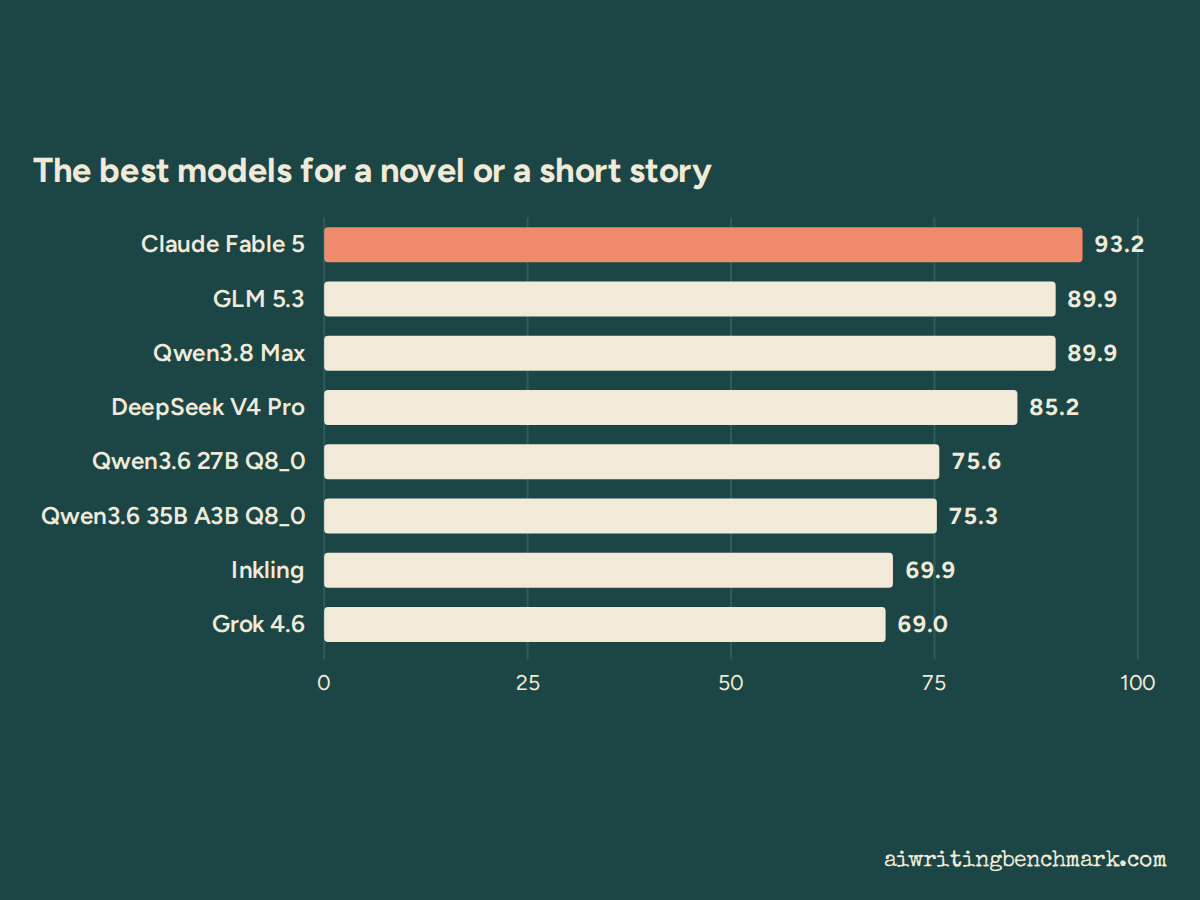
Writing model ranking based on pairwise results
RankModelAI judge scoreHuman score
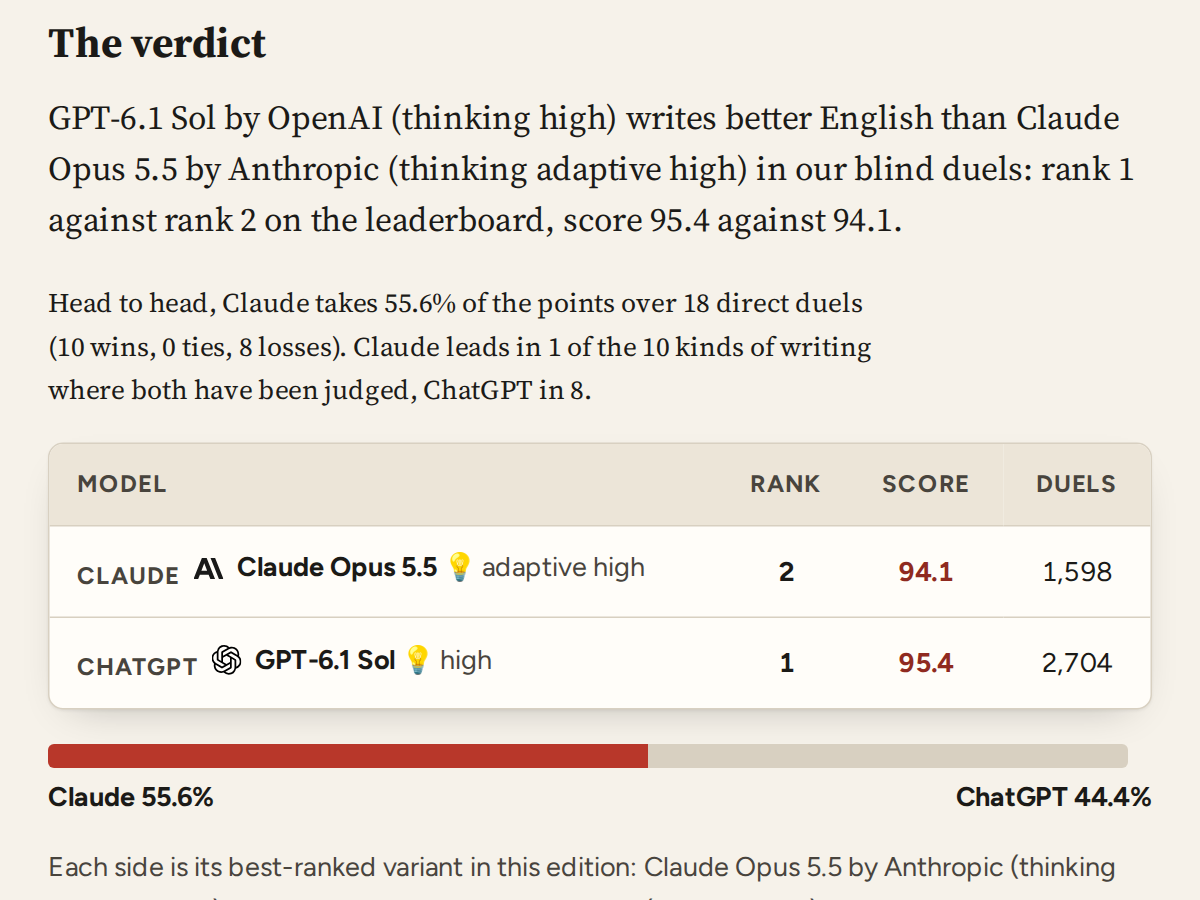
1GPT-6.1 Sol 💡 high95.0—
2Claude Fable 5.2 💡 adaptive high92.6—
3Kimi K3.1 Pro 💡 high92.0—
4Claude Opus 5.5 💡 adaptive high91.3—
4GPT-6 Astra 💡 high91.3—
6Kimi K3 💡 enabled90.2—
7Claude Fable 5 💡 adaptive high88.5—
8Claude Sonnet 5.5 💡 adaptive high88.1—
9Claude Fable 5.1 💡 adaptive high87.3—
10GPT-6.1 Terra 💡 high87.0—
11GPT-6 Sol 💡 high86.9—
12Claude Opus 5 💡 adaptive high86.7—
14GLM 5.3 💡 max85.9—
15Grok 4.7 💡 high84.4—
16Gemini 4 Hydrogen 💡 high84.2—
17Claude Sonnet 5 💡 adaptive high83.3—
18GPT-6 Luna 💡 high80.2—
19Aion 3.5 💡 high79.0—
20GPT-5.6 Sol 💡 high78.4—
21Muse Spark 1.3 💡 high78.0—
22Muse Ember 💡 high77.5—
23GLM 5.3 Flash 💡 high77.4—
24DeepSeek V4.1 Flash 💡 high77.2—
25MiniMax M3 💡 enabled75.6—
25Muse Spark 1.2 💡 high75.6—
27Gemini 3.8 Flash 💡 high74.2—
28Nemotron 3.5 Super VL 💡 high74.1—
29GLM 5.2 💡 enabled73.3—
29Hy3 💡 high73.3—
31Step 5 Preview fp8 💡 high72.7—
32Mercury 3 💡 high72.4—
33MiMo V2.6 Pro fp8 💡 high71.3—
34Qwen3.8 Max 💡 xhigh70.8—
35Qwen4 Max 💡 high70.7—
36Beam 1.0 💡 high70.5—
38Claude Haiku 5.5 💡 adaptive high70.0—
39Hy4 Preview 💡 high68.3—
41Aion 3.0 💡 mandatory67.0—
41Gemini 3.7 Flash 💡 medium67.0—
43Grok 4.6 💡 high66.4—
44GPT-5.6 Terra 💡 high64.7—
45Gemini 4 Argon 💡 high63.3—
45Ling 3.1 Flash 💡 high63.3—
48Ling 3.2 Flash 💡 high57.9—
49GPT-5.6 Luna 💡 high57.2—
50DeepSeek V4 Pro 💡 enabled57.1—
53Qwen3.6 27B Q8_0 💡 on* 🏠55.8—
54Qwen3.8 27B Q8_0 💡 xhigh** 🏠55.0—
55Qwen3.7 Max 💡 enabled54.9—
56Mistral Large 4 💡 high53.2—
57DeepSeek V4 Flash 💡 enabled52.4—
58Gemma 4 31B Q8_0 💡 on* 🏠51.657.6
60Qwen3.8 Flash 💡 high50.8—
61Inkling 💡 high49.0—
65Qwen3.7 Plus 💡 enabled47.8—
66MiMo V2.6 Flash 💡 high46.3—
68Qwen3.6 35B A3B Q8_0 💡 on* 🏠44.245.0
69MiMo V2.5 Pro 💡 enabled41.9—
69Nemotron 3 Ultra 💡 high41.9—
72Gemma 4 31B Q8_0 ↯ 🏠40.4—
75MiMo V2.5 💡 enabled39.3—
77Gemma 4 26B A4B Q8_0 💡 on* 🏠38.642.4
78Gemma 4 12B Q8_0 💡 on* 🏠37.955.0
83MiniMax M3.1 Flash 💡 high34.1—
85Gemma 4 12B Q8_0 ↯ 🏠32.3—
86Gemma 4 26B A4B Q8_0 ↯ 🏠30.5—
86Nemotron 3.5 Lightning 💡 high30.5—
86Seed 2.1 Turbo ↯30.5—
92Agnes 3.0 Flash 💡 high25.9—
93Granite 4.2 30B Q8_0 💡 full 🏠24.6—
94Qwen3.6 27B Q8_0 ↯ 🏠24.5—
98Flint V1.0 💡 high22.3—
99Mistral Medium 3.5 💡 high21.9—
100Qwen3.6 35B A3B Q8_0 ↯ 🏠19.5—
101Qwen3.8 27B Q8_0 ↯ 🏠18.3—
105Granite 4.2 8B Q8_0 💡 full 🏠17.2—
105Nemotron 3 Nano Omni 30B A3B Q8_0 💡 on* 🏠17.2—
108Gemma 4 E2B Q8_0 💡 on* 🏠15.3—
113Gemma 4 E4B Q8_0 💡 on* 🏠12.5—
115Gemma 4 E4B Q8_0 ↯ 🏠11.1—
118Gemma 4 E2B Q8_0 ↯ 🏠9.9—

121 models compared136,378 published AI verdicts

Method: regularized Bradley–Terry model. The AI-judge score determines rank; the human score is independent and remains secondary until more community votes are available. A score of 50 means an estimated one-in-two chance of beating the average model in this language and category.

Direct duel results

Each cell shows the share of available points earned by the row model against the column model: a win is worth 100%, a tie 50%, and a loss 0%. This result matrix uses only the compatible evaluation protocols included in the main ranking.

Directional matrix of points earned in direct duels. Values above 50% favour the row model; values below 50% favour the column model.

0 %100 %

💡 marks a model with reasoning, ↯ one without reasoning. 🏠 marks a model run locally on the site author’s computer.“on*”: the local file only has an on/off switch for reasoning, so no level can be chosen and the model runs at its default. “xhigh**”: Qwen3.8 27B runs at its documented default level, xhigh; high is not available on this model. For Muse Glimmer 30B and Ling 3.0 Flash (high) and for Granite 4.2 and Nemotron 3 Super (full), the level shown is the model’s documented default.

View as a data table
Points earned in direct duels by model pair
Model

Published duel coverage

Each cell shows how many published AI-judged duels across all published evaluation protocols compare the two models for this language and category. The models on both axes are candidates; this matrix does not show which judge produced each verdict.

Symmetric matrix of published duel counts. The diagonal is zero because a model is not compared with itself.

0

💡 marks a model with reasoning, ↯ one without reasoning. 🏠 marks a model run locally on the site author’s computer.“on*”: the local file only has an on/off switch for reasoning, so no level can be chosen and the model runs at its default. “xhigh**”: Qwen3.8 27B runs at its documented default level, xhigh; high is not available on this model. For Muse Glimmer 30B and Ling 3.0 Flash (high) and for Granite 4.2 and Nemotron 3 Super (full), the level shown is the model’s documented default.

View as a data table
Published duel counts by model pair
Model

Help elect the best LLM for writing in English

Which model writes the better text? Judge this anonymous pair and contribute to the human ranking. Model names stay hidden during the duel and are revealed only after your choice.

Arena