My name is Johannes Eva, and I have been building websites for 27 years. The AI Writing Benchmark began with a gap: no existing leaderboard measured what interested me, the writing quality of AI models in English and other languages.
Public benchmarks mainly focus on code, mathematics and reasoning. The small part devoted to writing is usually evaluated only in English. Here, only the quality of the generated texts counts. The prompts are written directly in each language, and the answers are compared blindly.
Models that can run at home have a special place here. Gemma 4, Qwen 3.6 and 3.8, Ling 3.0 Flash, Muse Glimmer and Granite 4.2, among others, are marked with 🏠. They were run locally, in several quantisations, and their reasoning on and off.
This site is a personal project. No model provider pays me, and I have no reason to favour one model over another.
The machines used for local models
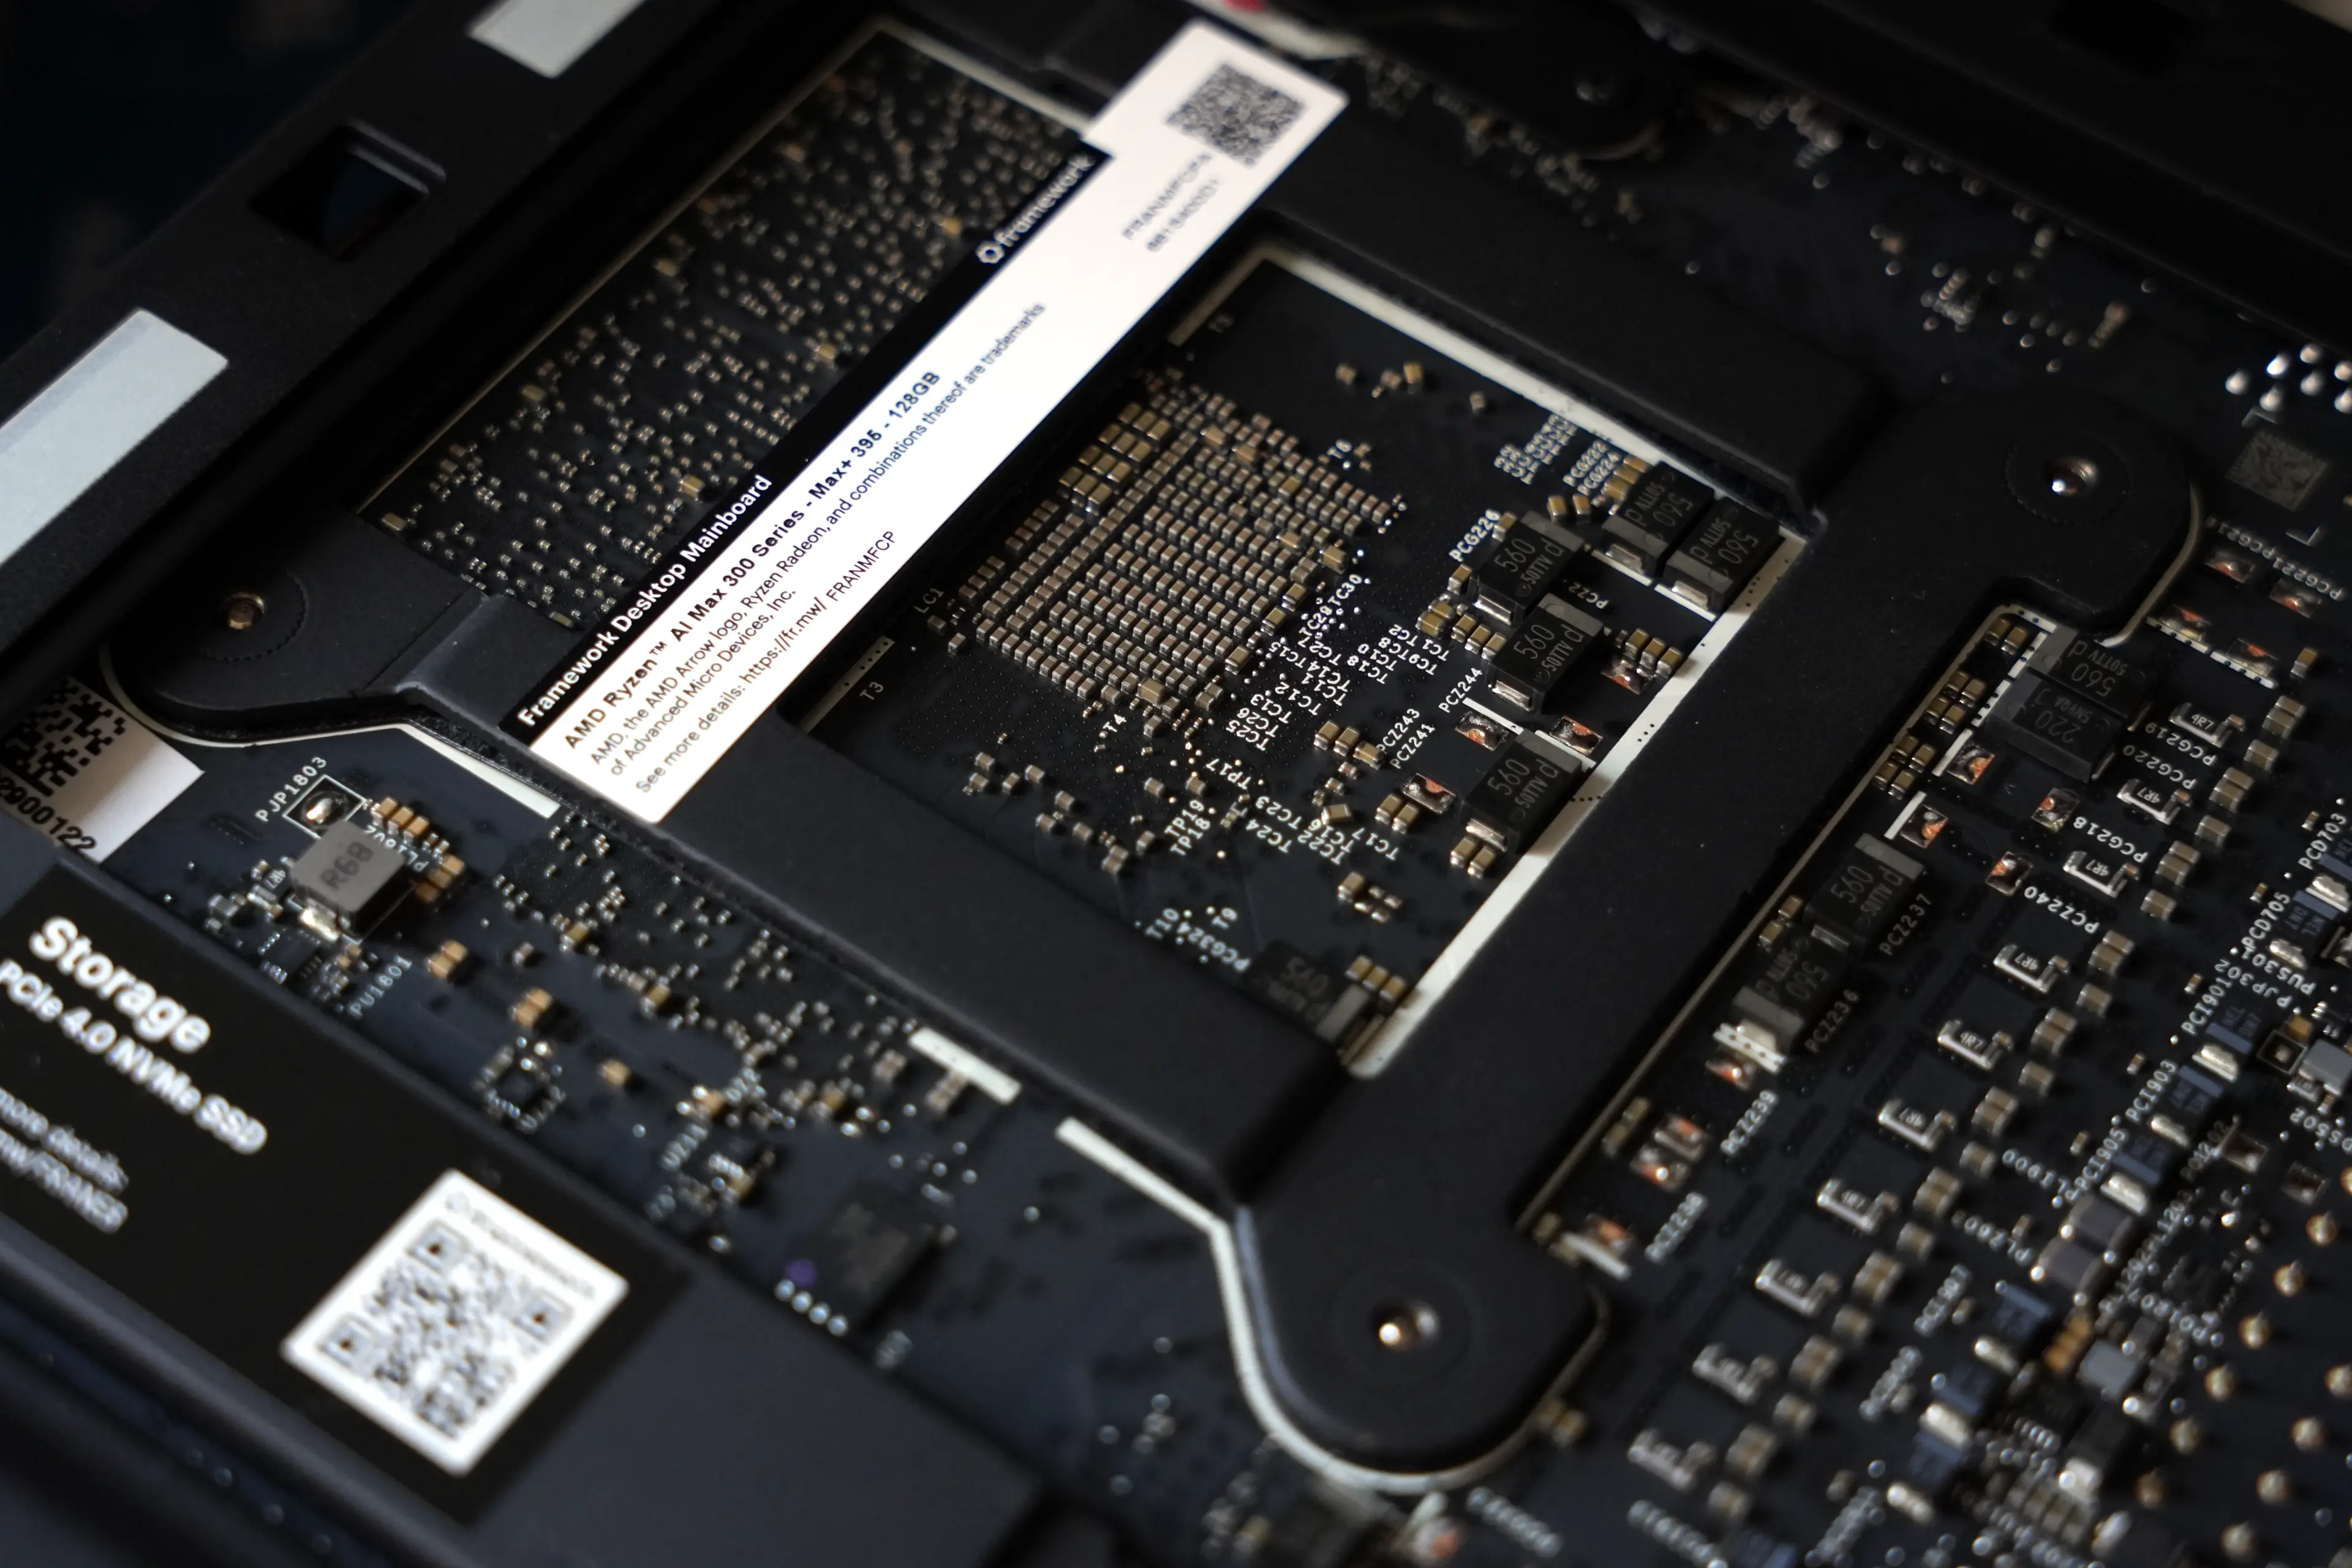
- Computer
- Framework Desktop, AMD Ryzen AI Max 300 Series, revision A6
- Processor
- AMD Ryzen AI Max+ 395, 16 cores and 32 threads, up to 5.19 GHz
- Graphics
- AMD Radeon 8060S integrated graphics
- Memory
- 128 GB of unified memory, shared by the processor and graphics unit
Local models run on a Framework Desktop with an AMD Ryzen AI Max+ 395 and 128 GB of unified memory available to both the processor and graphics unit. This makes it possible to load models larger than most consumer graphics cards can hold. A second machine with an NVIDIA GeForce RTX 5070 Ti contributes the smaller models.
Observed local generation speed (Strix Halo)
Median tokens generated per second on the Strix Halo machine (Framework Desktop, Ryzen AI Max+ 395) across valid benchmark responses generated there, including reasoning tokens. Speed varies with context length and software. Models without enough Strix Halo measurements are not listed.
| Model | Quantisation | Median speed | Responses |
|---|---|---|---|
| Gemma 4 26B A4B | Q8_0 | 39.8 tokens/s | 465 |
| Gemma 4 E2B | Q4_K_M | 39.4 tokens/s | 224 |
| Gemma 4 E4B | Q8_0 | 35.9 tokens/s | 542 |
| Gemma 4 E2B | Q6_K | 33.2 tokens/s | 216 |
| Ling 3.0 Flash | Q4_K_M | 31.6 tokens/s | 277 |
| Ling 3.0 Flash | Q4_K_M | 30.5 tokens/s | 240 |
| Gemma 4 E2B | Q8_0 | 29.2 tokens/s | 224 |
| Gemma 4 26B A4B QAT | QAT-Q4_0 | 27.9 tokens/s | 118 |
| Qwen3.6 35B A3B | Q4_K_M | 26.6 tokens/s | 347 |
| Nemotron 3 Nano Omni | Q4_K_M | 25.1 tokens/s | 960 |
| Gemma 4 E4B | Q4_K_M | 22.4 tokens/s | 221 |
| Qwen3.6 35B A3B | Q8_0 | 22.1 tokens/s | 312 |
| Nemotron 3 Nano Omni | Q8_0 | 21.2 tokens/s | 391 |
| Nemotron 3 Super | Q4_K_M | 21.1 tokens/s | 413 |
| Gemma 4 26B A4B | Q6_K | 20.2 tokens/s | 539 |
| Gemma 4 E4B | Q6_K | 18.6 tokens/s | 218 |
| Granite 4.2 8B | Q4_K_M | 16.9 tokens/s | 36 |
| Gemma 4 12B | Q8_0 | 14.6 tokens/s | 124 |
| Gemma 4 12B QAT | QAT-Q4_0 | 11 tokens/s | 752 |
| Gemma 4 31B QAT | QAT-Q4_0 | 10 tokens/s | 548 |
| Gemma 4 12B | Q6_K | 9 tokens/s | 216 |
| Qwen3.8 27B | Q4_K_M | 8.9 tokens/s | 546 |
| Muse Glimmer 30B Kquant 17gb | K-Quant 17GB | 8.8 tokens/s | 394 |
| Qwen3.8 27B | Q8_0 | 8.4 tokens/s | 498 |
| Muse Glimmer 30B Kquant Dynamic | K-Quant Dynamic | 8 tokens/s | 397 |
| Granite 4.2 30B | Q4_K_M | 7.6 tokens/s | 423 |
| Qwen3.6 27B | Q8_0 | 7.5 tokens/s | 190 |
| Qwen3.8 27B | Q6_K | 7 tokens/s | 504 |
| Granite 4.2 30B | Q6_K | 6.6 tokens/s | 397 |
| Gemma 4 31B | Q6_K | 5.8 tokens/s | 527 |
| Qwen3.6 27B | Q4_K_M | 5.2 tokens/s | 588 |
| Granite 4.2 30B | Q8_0 | 4.9 tokens/s | 447 |
| Gemma 4 31B | Q8_0 | 4.8 tokens/s | 316 |