The full leaderboard
Every model ranked on English writing, with filters by kind of writing, publisher, size, reasoning mode and quantization, and the duel matrices.
New models as they enter the ranking, where they land against their predecessor, the new analyses and the milestones of the benchmark.
131,920 ranked verdicts
121 ranked models
18,080 to go before 150,000
Cumulative totals of the English edition, day by day.
Ranks and scores are today’s: they are recomputed with every new verdict, not frozen when a model arrives.

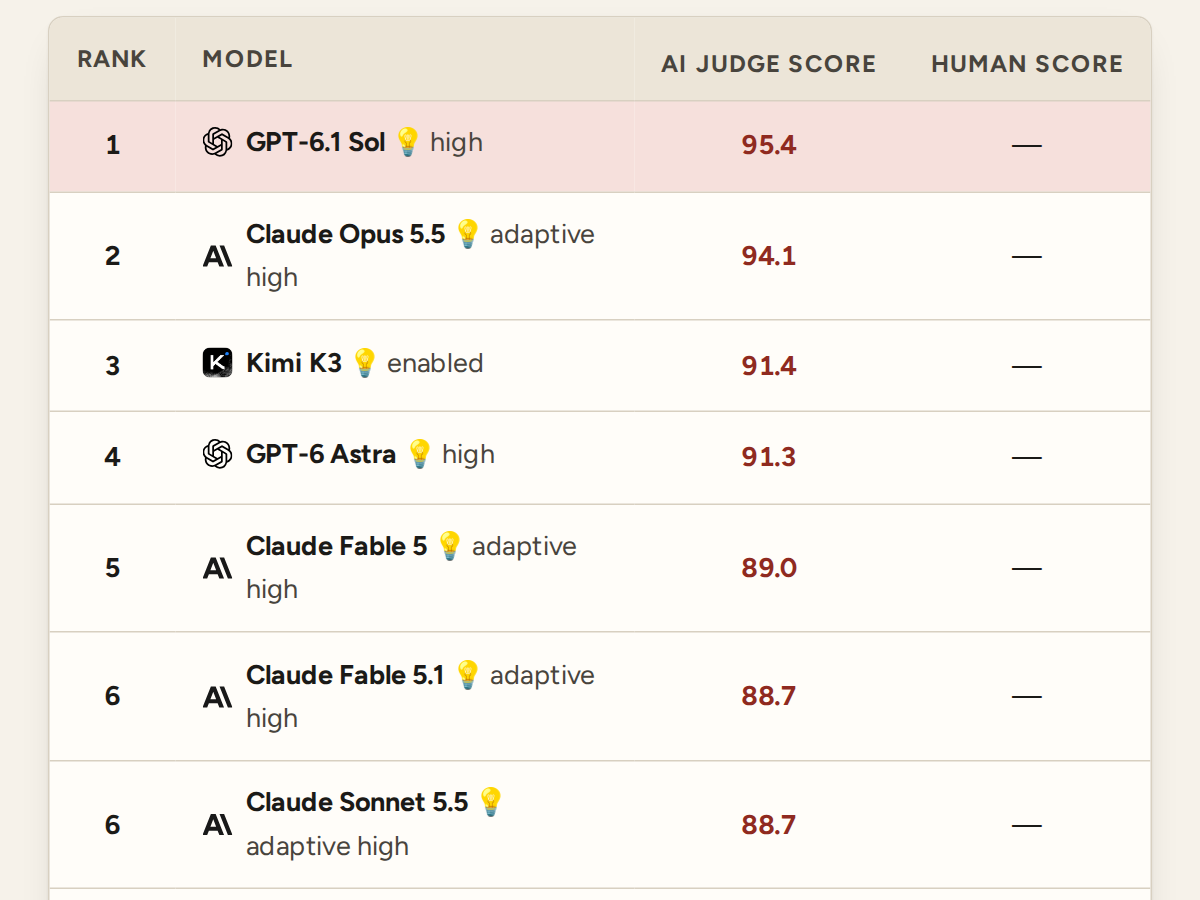
Claude Fable 5.2. Now No. 2 of 121, with a score of 92.6. That is 5.3 points above its predecessor, Claude Fable 5.1 (No. 9, 87.3).

Qwen4 Max. Now No. 35 of 121, with a score of 70.7. Level with its predecessor, Qwen3.8 Max (No. 34, 70.8).

Flint V1.0. Now No. 98 of 121, with a score of 22.3.

Gemini 4 Hydrogen. Now No. 16 of 121, with a score of 84.2.

Ling 3.2 Flash. Now No. 48 of 121, with a score of 57.9.

Muse Ember. Now No. 22 of 121, with a score of 77.5.
125,000
Reached 112 days after the first duel, 34 days after the 100,000 mark.
Kimi K3.1 Pro. Now No. 3 of 121, with a score of 92.0. That is 1.8 points above its predecessor, Kimi K3 (No. 6, 90.2). Direct duels won against it: 9 of 13 (69%).

GPT-6.1 Terra. Now No. 10 of 121, with a score of 87.0. That is 22.3 points above its predecessor, GPT-5.6 Terra (No. 44, 64.7).

Mercury 3. Now No. 32 of 121, with a score of 72.4.

Beam 1.0. Now No. 36 of 121, with a score of 70.5.
Gemini 4 Argon. Now No. 45 of 121, with a score of 63.3.

MiniMax M3.1 Flash. Now No. 83 of 121, with a score of 34.1.
Nemotron 3.5 Super VL. Now No. 28 of 121, with a score of 74.1.

Step 5 Preview. Now No. 31 of 121, with a score of 72.7.
Ling 3.1 Flash. Now No. 45 of 121, with a score of 63.3.

Mistral Large 4. Now No. 56 of 121, with a score of 53.2.
Nemotron 3 Ultra. Now No. 69 of 121, with a score of 41.9.
Nemotron 3.5 Lightning. Now No. 86 of 121, with a score of 30.5.
Claude Haiku 5.5. Now No. 38 of 121, with a score of 70.0.
100,000
Reached 78 days after the first duel, 8 days after the 75,000 mark.
Until now, most duels compared personal messages. New duels are spread across the ten categories (letters, articles, fiction, speeches, reports…), starting with the least covered, so the ranking gradually reflects every kind of text.
Muse Spark 1.3, which kept sliding down the ranking, no longer judges; its past verdicts stay published. Claude Opus 5.5 takes over its share, so the duels arrive at the same pace.
In the Duel and on the head-to-head pages, responses now show their bold text, headings and lists instead of raw asterisks and hashes, so you judge the text the way a reader would see it.
About one verdict in twenty came from a judge facing its own model, and it tended to favour itself: up to five points for some models. Those verdicts stay published on the judges’ page but no longer enter the ranking, and judges are no longer given their own model.
GPT-6.1 Sol. Now No. 1 of 121, with a score of 95.0. That is 8.1 points above its predecessor, GPT-6 Sol (No. 11, 86.9). Direct duels won against it: 14 of 18 (78%).
100
With Claude Sonnet 5.5, 73 days after the first duel.

Aion 3.5. Now No. 19 of 121, with a score of 79.0. That is 12.0 points above its predecessor, Aion 3.0 (No. 41, 67.0).
Claude Sonnet 5.5. Now No. 8 of 121, with a score of 88.1. That is 4.8 points above its predecessor, Claude Sonnet 5 (No. 17, 83.3).
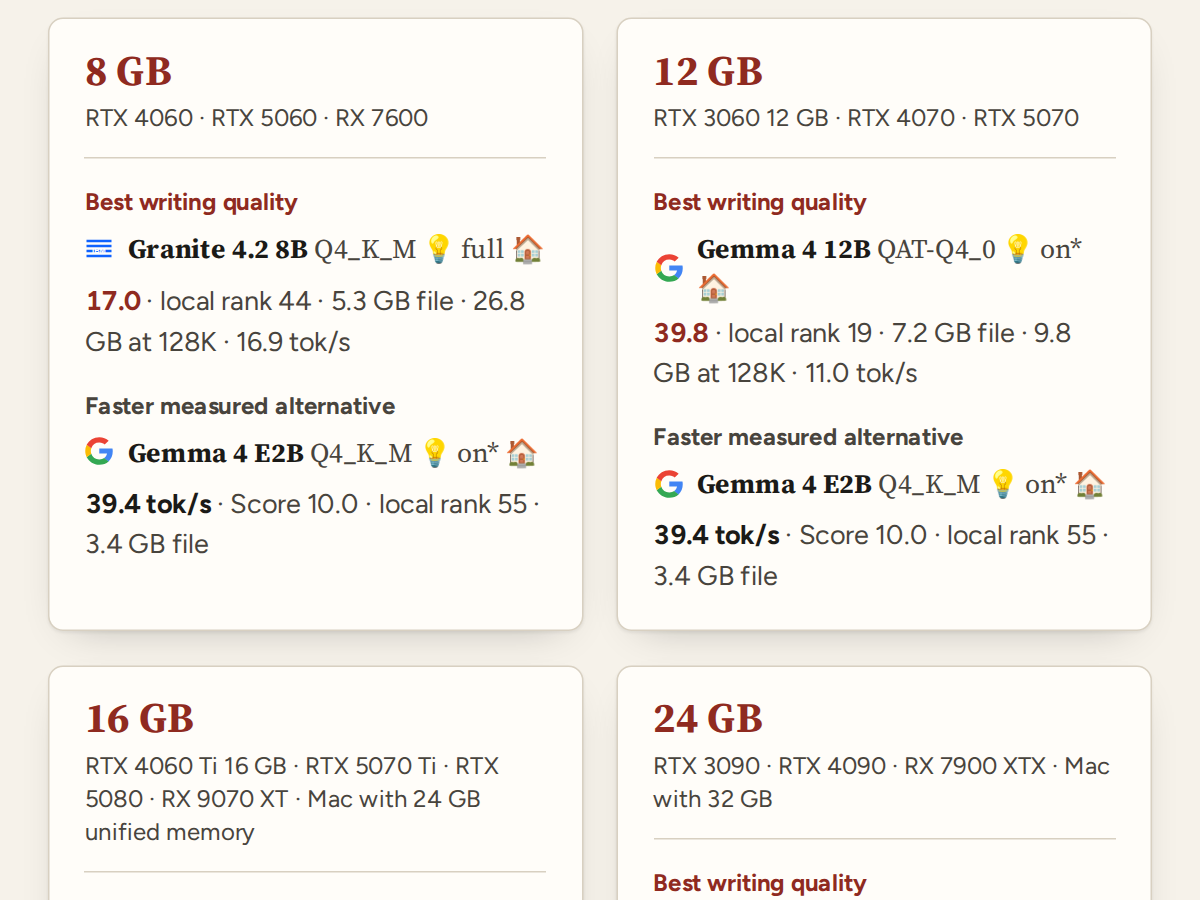
The Local AI ranking shows the memory each model needs as a file and with a 128K or 256K context, in GGUF or MLX and with an F16 or Q8 cache. Buttons above every ranking switch between the latest models, the previous generation and older ones.
75,000
Reached 70 days after the first duel, 12 days after the 50,000 mark.
Claude Opus 5.5. Now No. 4 of 121, with a score of 91.3. That is 4.6 points above its predecessor, Claude Opus 5 (No. 12, 86.7).
GPT-6 Luna. Now No. 18 of 121, with a score of 80.2. That is 23.0 points above its predecessor, GPT-5.6 Luna (No. 49, 57.2).
GPT-6 Sol. Now No. 11 of 121, with a score of 86.9. That is 8.5 points above its predecessor, GPT-5.6 Sol (No. 20, 78.4).
The newest Anthropic and OpenAI models take over as judges, alongside Muse Spark 1.3. Each verdict still compares two anonymous texts written for the same prompt.

Agnes 3.0 Flash. Now No. 92 of 121, with a score of 25.9.

Grok 4.7. Now No. 15 of 121, with a score of 84.4. That is 18.0 points above its predecessor, Grok 4.6 (No. 43, 66.4). Direct duels won against it: 4 of 10 (40%).

MiMo V2.6 Flash. Now No. 66 of 121, with a score of 46.3.
MiMo V2.6 Pro. Now No. 33 of 121, with a score of 71.3. That is 29.4 points above its predecessor, MiMo V2.5 Pro (No. 69, 41.9). Direct duels won against it: 31 of 40 (78%).
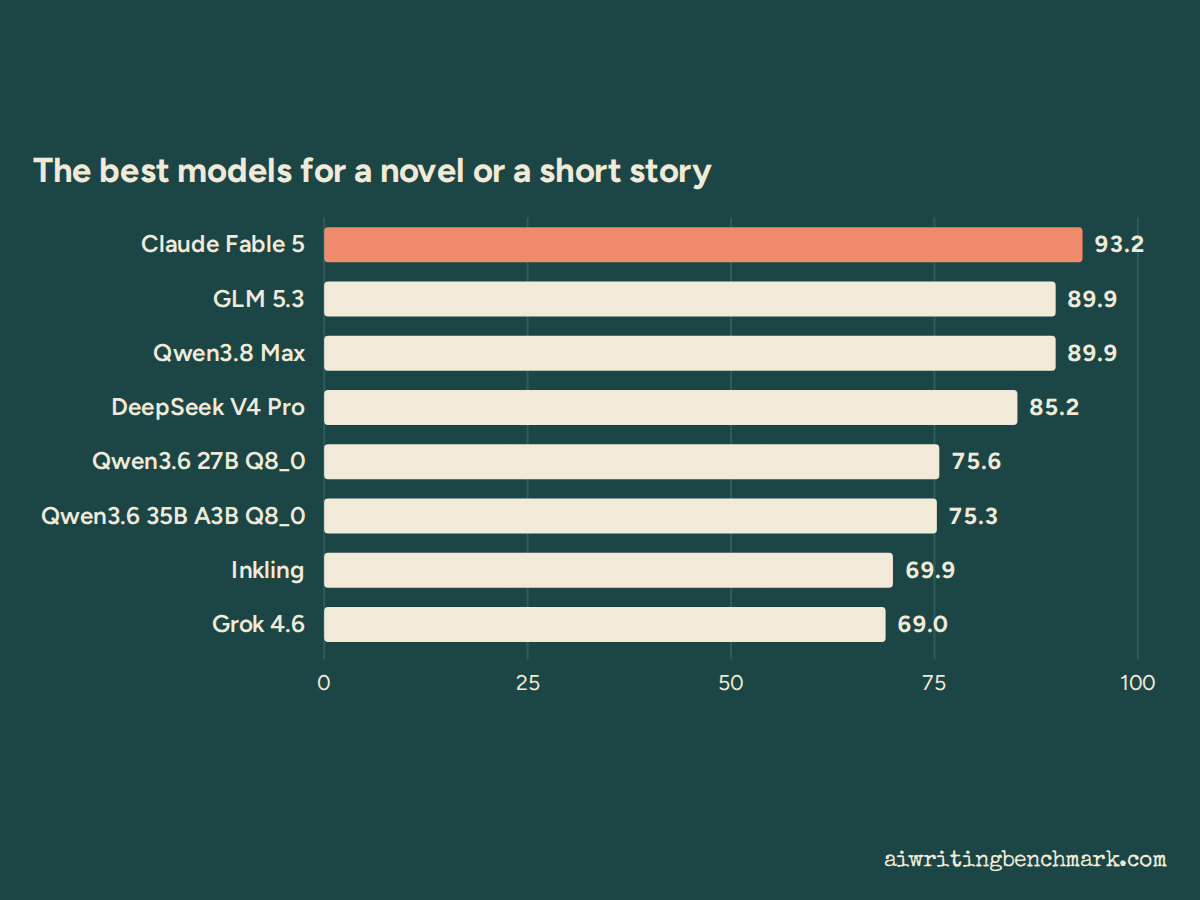 Which AI for a novel, an email, a cover letter or an essay? The best model changes with the task
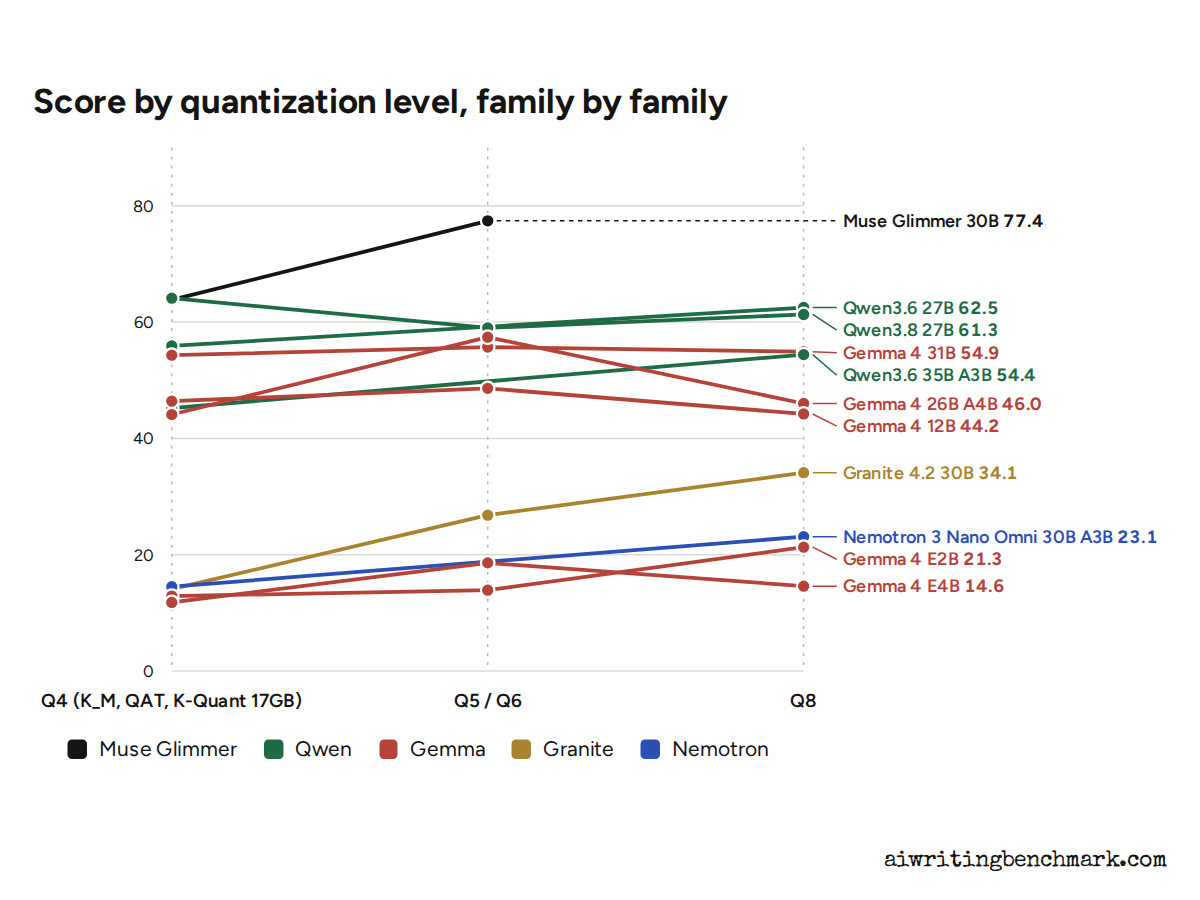 Q4, Q6 or Q8: quantization costs nothing on some models and twenty points on others
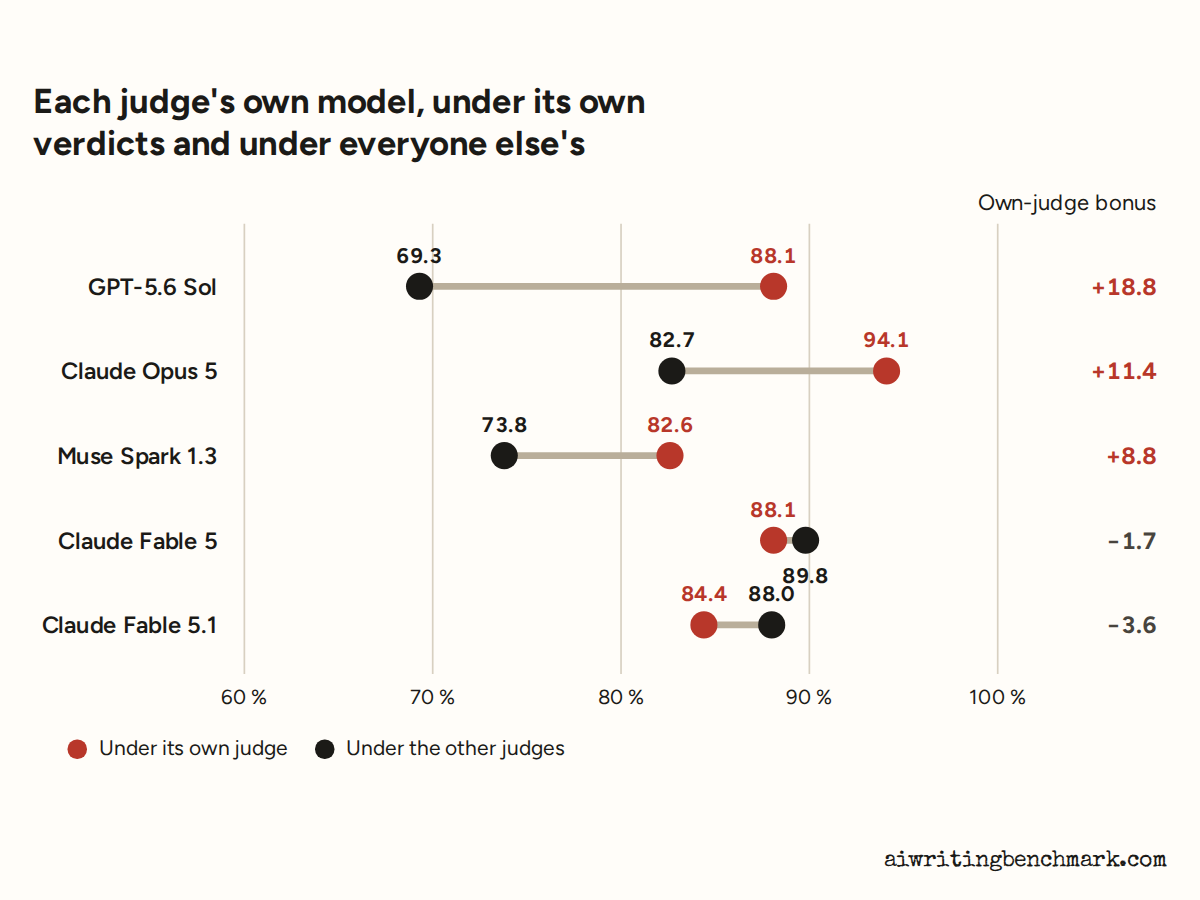 Do AI judges favour their own model? Two of five do, by up to 19 points
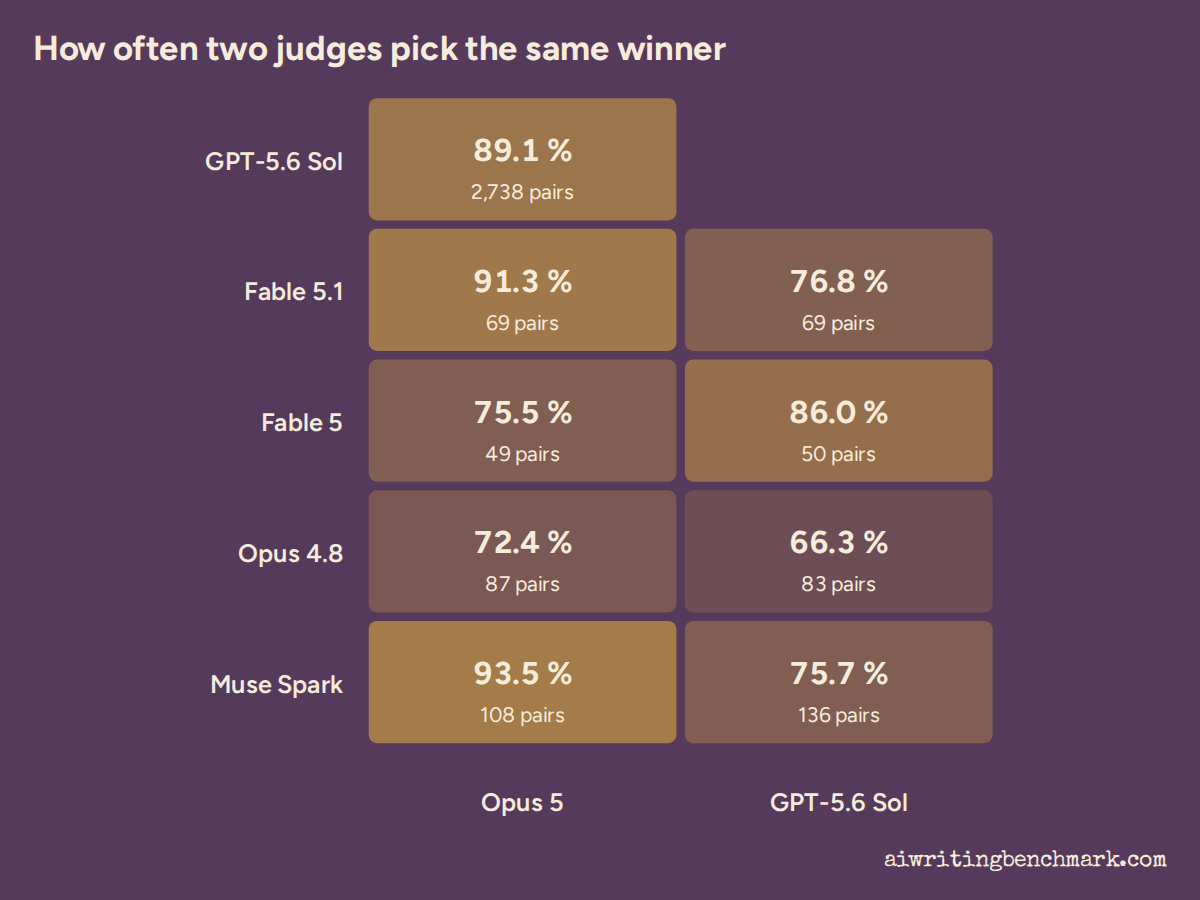 The two main AI judges pick the same winner nine times out of ten. The disagreements are elsewhere
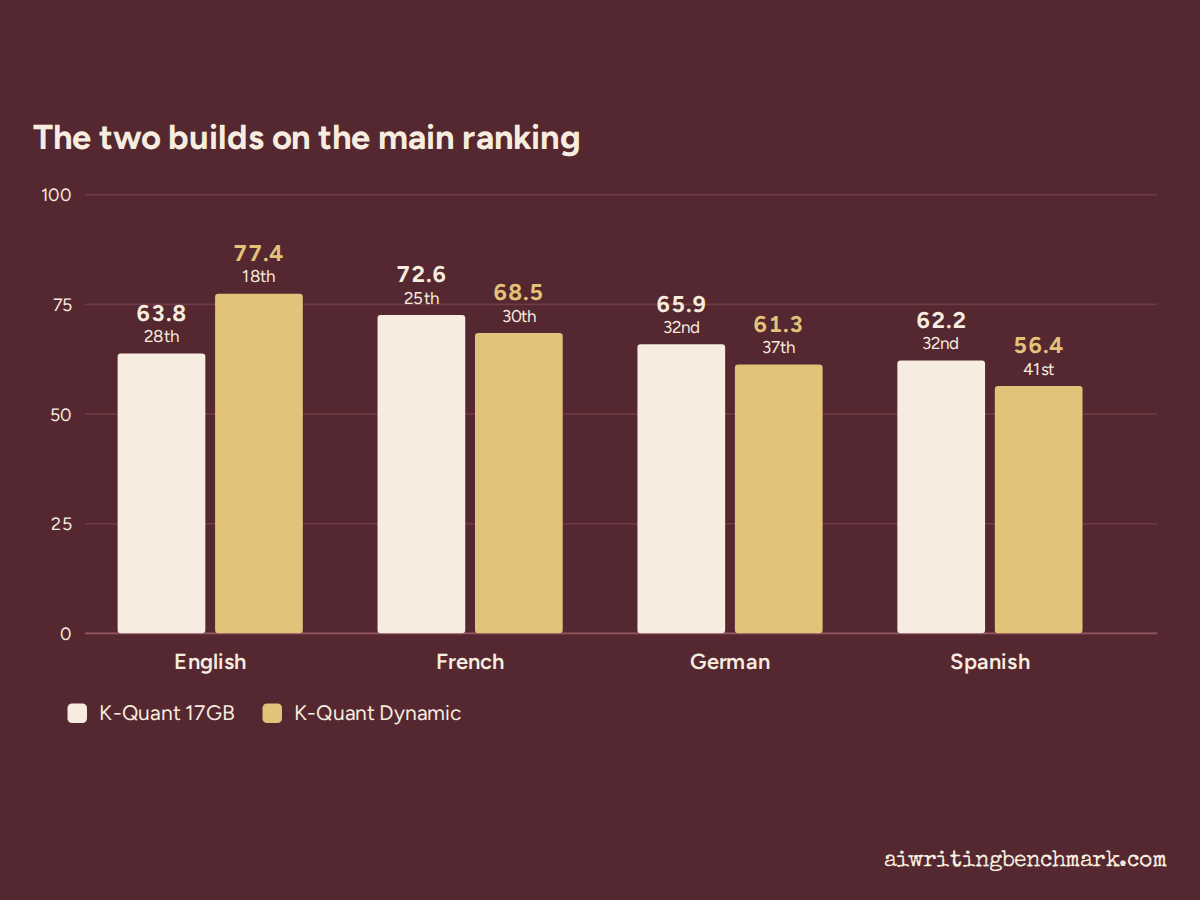
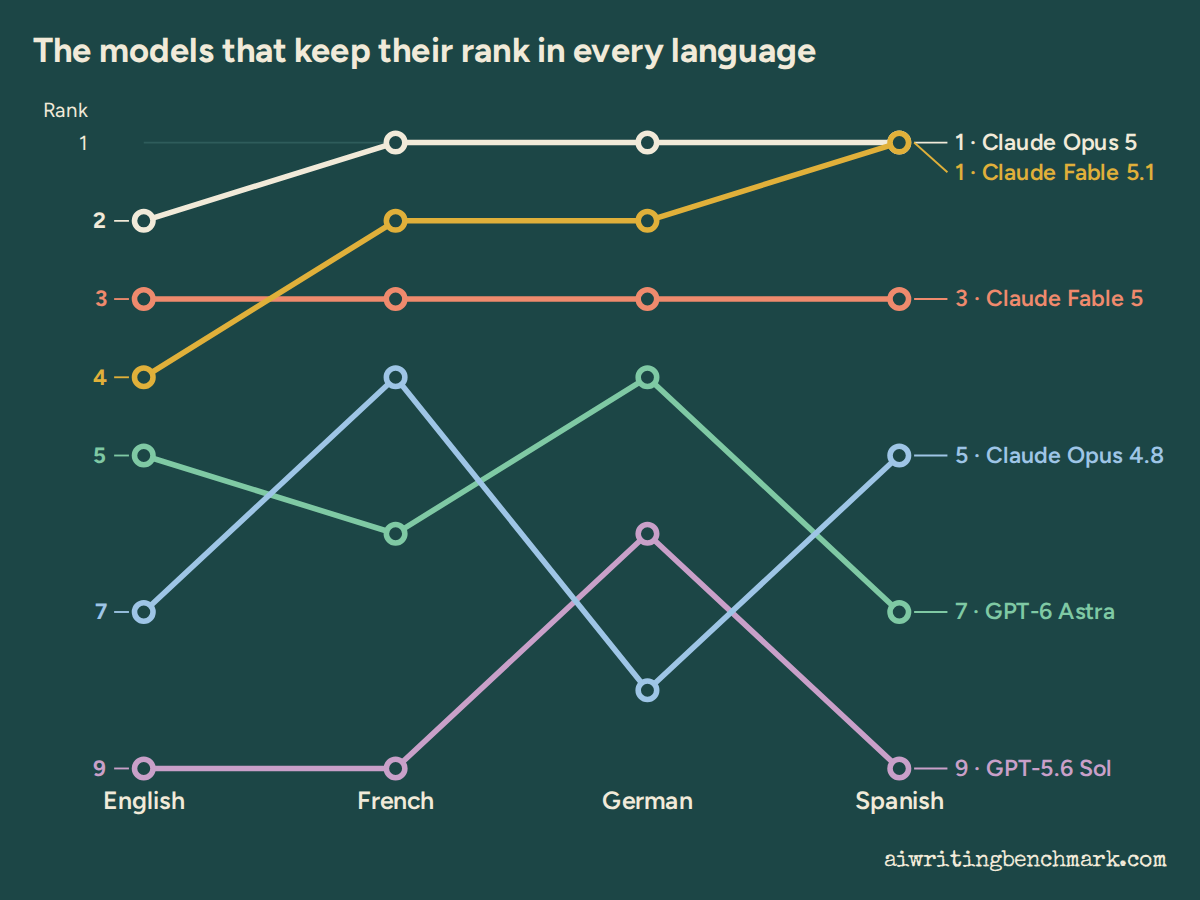 Same model, four languages: the top barely moves, the middle swings by forty places
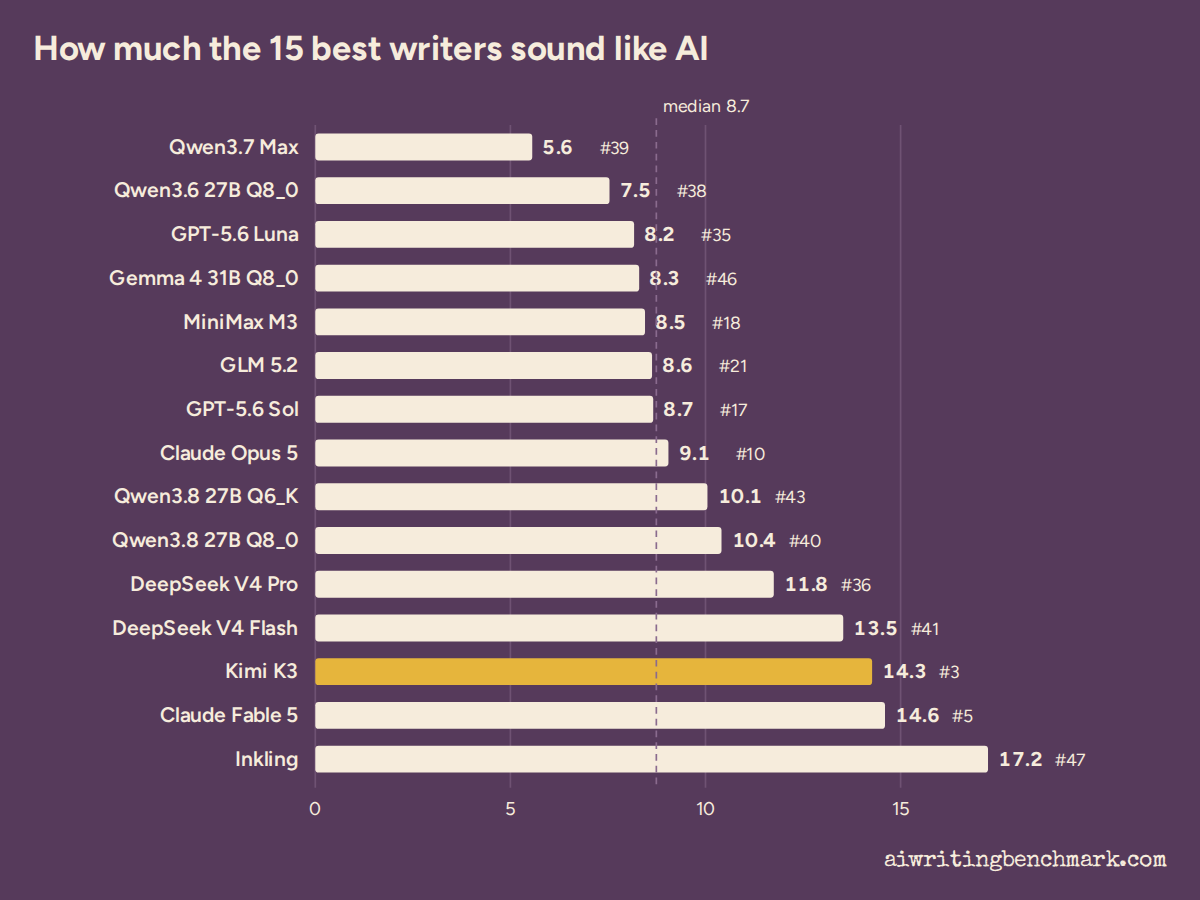 Which AI sounds least like AI? The best writers are the heaviest em-dash users
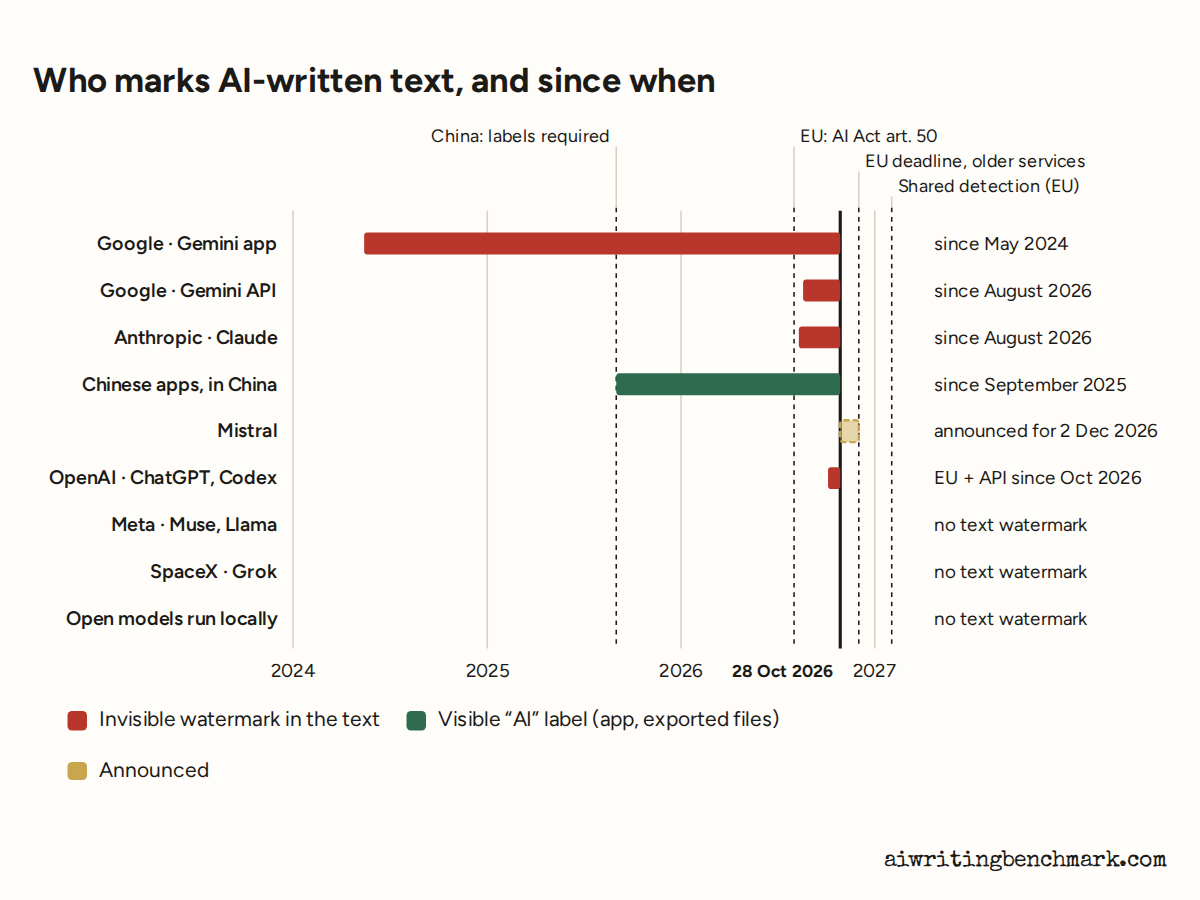
Claude vs ChatGPT, Claude vs Gemini, Gemma vs Qwen: the most-searched match-ups now have their own page, with the verdict of the blind duels. Every ranked model also gets an index of the marks of machine prose: stock phrases, em dashes, lists of three.
Ling 3.0 Flash. Now No. 84 of 121, with a score of 33.4. Best of its 2 ranked variants: Ling 3.0 Flash by InclusionAI (Q4_K_M, no thinking).
50,000
Reached 58 days after the first duel, 20 days after the 25,000 mark.

DeepSeek V4.1 Flash. Now No. 24 of 121, with a score of 77.2. That is 24.8 points above its predecessor, DeepSeek V4 Flash (No. 57, 52.4).
GPT-6 Astra. Now No. 4 of 121, with a score of 91.3.
Claude Fable 5.1. Now No. 9 of 121, with a score of 87.3. That is 1.2 points below its predecessor, Claude Fable 5 (No. 7, 88.5).
Gemini 3.8 Flash. Now No. 27 of 121, with a score of 74.2. That is 7.0 points above its predecessor, Gemini 3.6 Flash (No. 40, 67.2).
Muse Spark 1.3. Now No. 21 of 121, with a score of 78.0. That is 2.4 points above its predecessor, Muse Spark 1.2 (No. 25, 75.6).
Inkling. Now No. 61 of 121, with a score of 49.0.

Granite 4.2 8B. Now No. 105 of 121, with a score of 17.2. Best of its 2 ranked variants: Granite 4.2 8B by IBM (Q8_0, thinking full).

GLM 5.3 Flash. Now No. 23 of 121, with a score of 77.4.
Granite 4.2 30B. Now No. 93 of 121, with a score of 24.6. Best of its 3 ranked variants: Granite 4.2 30B by IBM (Q8_0, thinking full).

Hy4 Preview. Now No. 39 of 121, with a score of 68.3. That is 5.0 points below its predecessor, Hy3 (No. 29, 73.3). Direct duels won against it: 7 of 24 (29%).
Qwen3.8 Flash. Now No. 60 of 121, with a score of 50.8.
25,000
Reached 38 days after the first duel.
75
With Muse Spark 1.2, 34 days after the first duel.
Aion 3.0. Now No. 41 of 121, with a score of 67.0.
Gemini 3.7 Flash. Now No. 41 of 121, with a score of 67.0.
GLM 5.3. Now No. 14 of 121, with a score of 85.9. That is 12.6 points above its predecessor, GLM 5.2 (No. 29, 73.3). Direct duels won against it: 17 of 24 (71%).
Grok 4.6. Now No. 43 of 121, with a score of 66.4.
Hy3. Now No. 29 of 121, with a score of 73.3.
Mistral Medium 3.5. Now No. 99 of 121, with a score of 21.9.
Muse Spark 1.2. Now No. 25 of 121, with a score of 75.6.
Qwen3.8 Max. Now No. 34 of 121, with a score of 70.8. That is 15.9 points above its predecessor, Qwen3.7 Max (No. 55, 54.9).

Seed 2.1 Turbo. Now No. 86 of 121, with a score of 30.5.
Qwen3.8 27B. Now No. 51 of 121, with a score of 56.7. Best of its 6 ranked variants: Qwen3.8 27B by Alibaba (Q4_K_M, thinking xhigh). That is 0.9 points above its predecessor, Qwen3.6 27B (No. 53, 55.8).
50
With Gemma 4 12B, 28 days after the first duel.
Muse Glimmer 30B. Now No. 37 of 121, with a score of 70.3. Best of its 2 ranked variants: Muse Glimmer 30B by Meta (K-Quant Dynamic, thinking high).
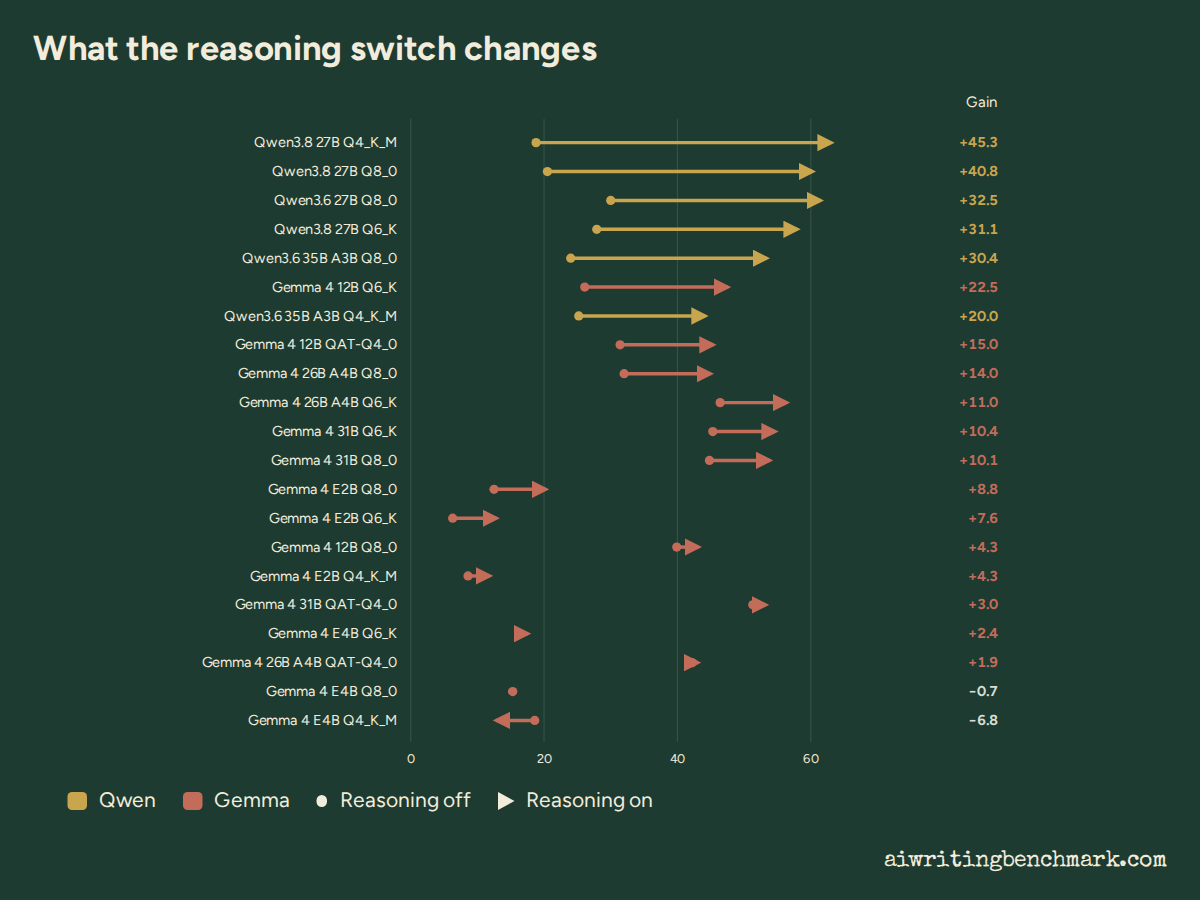
Gemma 4 E2B. Now No. 108 of 121, with a score of 15.3. Best of its 6 ranked variants: Gemma 4 E2B by Google (Q8_0, thinking on).
Gemma 4 E4B. Now No. 109 of 121, with a score of 14.6. Best of its 6 ranked variants: Gemma 4 E4B by Google (Q6_K, no thinking).
Nemotron 3 Super 120B A12B. Now No. 91 of 121, with a score of 26.2.

Laguna S 2.1 UD. Now No. 80 of 121, with a score of 36.6.
Nemotron 3 Nano Omni 30B A3B. Now No. 105 of 121, with a score of 17.2. Best of its 2 ranked variants: Nemotron 3 Nano Omni 30B A3B by NVIDIA (Q8_0, thinking on).
Claude Sonnet 5. Now No. 17 of 121, with a score of 83.3.
Gemini 3.6 Flash. Now No. 40 of 121, with a score of 67.2.
Claude Opus 5. Now No. 12 of 121, with a score of 86.7. Level with its predecessor, Claude Opus 4.8 (No. 13, 86.3).
GPT-5.6 Luna. Now No. 49 of 121, with a score of 57.2.
Kimi K3. Now No. 6 of 121, with a score of 90.2.
Claude Fable 5. Now No. 7 of 121, with a score of 88.5.
25
With Claude Opus 4.8, 6 days after the first duel.
Claude Opus 4.8. Now No. 13 of 121, with a score of 86.3.
GPT-5.6 Terra. Now No. 44 of 121, with a score of 64.7.
GPT-5.6 Sol. Now No. 20 of 121, with a score of 78.4.
Gemma 4 12B. Now No. 74 of 121, with a score of 39.4. Best of its 6 ranked variants: Gemma 4 12B by Google (Q6_K, thinking on).
MiniMax M3. Now No. 25 of 121, with a score of 75.6.
Gemma 4 26B A4B. Now No. 64 of 121, with a score of 48.3. Best of its 6 ranked variants: Gemma 4 26B A4B by Google (Q6_K, thinking on).
Qwen3.6 35B A3B. Now No. 68 of 121, with a score of 44.2. Best of its 4 ranked variants: Qwen3.6 35B A3B by Alibaba (Q8_0, thinking on).
DeepSeek V4 Pro. Now No. 50 of 121, with a score of 57.1. Best of its 2 ranked variants: DeepSeek V4 Pro by DeepSeek (thinking on).
Gemma 4 31B. Now No. 58 of 121, with a score of 51.6. Best of its 6 ranked variants: Gemma 4 31B by Google (Q8_0, thinking on).
GLM 5.2. Now No. 29 of 121, with a score of 73.3.
MiMo V2.5 Pro. Now No. 69 of 121, with a score of 41.9. Best of its 2 ranked variants: MiMo V2.5 Pro by Xiaomi (thinking on).
Mistral Medium 3.5 128B. Now No. 97 of 121, with a score of 22.9.
Qwen3.6 27B. Now No. 53 of 121, with a score of 55.8. Best of its 3 ranked variants: Qwen3.6 27B by Alibaba (Q8_0, thinking on).
Qwen3.7 Max. Now No. 55 of 121, with a score of 54.9. Best of its 2 ranked variants: Qwen3.7 Max by Alibaba (thinking on).
Every model ranked on English writing, with filters by kind of writing, publisher, size, reasoning mode and quantization, and the duel matrices.
A live ranking of open-weight models for English writing, what each file needs in memory, and what fits in 16, 24, 32 or 128 GB.
Data-led articles on the judges, quantization, reasoning mode and the four languages.